From 1,000 Users to a Million: How Backend Engineering Priorities Shift as a Platform Grows Up
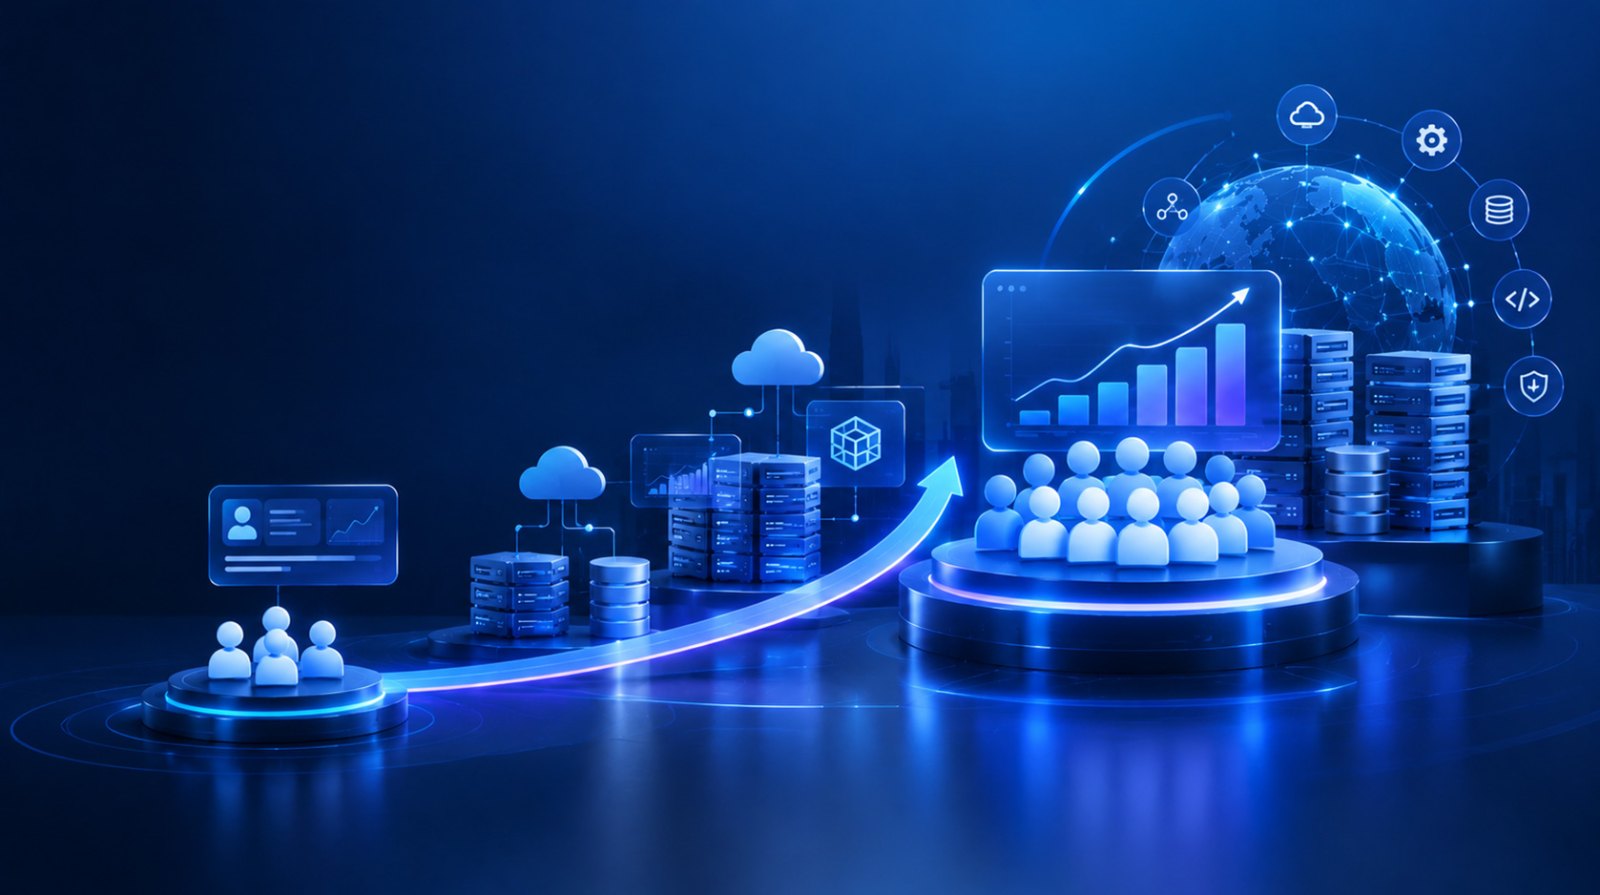
The backend that carried a product to its first 1,000 users rarely carries it to its first million. That is not an indictment of the original design. It is what happens when the questions change.
In the early days, engineers asked whether anyone wanted the product. Years later, the same team juggles terabytes of data, dozens of partner connections, tighter uptime promises, and several squads pushing changes into one codebase. When a growing system meets a complex problem its original design never anticipated, companies sometimes bring in specialists such as SysGears’ JVM engineering team, and priorities must shift to meet the new constraints.
There is no universal maturity ladder: a profitable SaaS product can live happily as a monolith for years, while another needs distributed processing in its second year. So, maturity is judged by the problems a team can solve calmly, not the technologies it has adopted.
Day One Needs Room to Move, Not Room to Grow
A young product has more uncertainty than traffic, which makes flexibility worth more than raw capacity. A modular monolith on PostgreSQL, hosted on a managed service such as Amazon RDS, Google Cloud SQL or Azure Database, is often plentiful: fewer moving parts, an easy-to-follow codebase, and no release negotiations across a web of services.
Designing for hypothetical traffic carries a price tag. Microservices bring service discovery, network calls, tracing and questions about data ownership. Kubernetes adds an operational layer. Kafka earns its place when a system genuinely needs event streaming, yet it is an expensive answer to a problem a database transaction or simple queue already solves. These tools are not too complicated; they are simply poor investments before the business has the problems they were made for.
Some early choices do stick. Authentication, data modeling, module boundaries, and security form the foundation that is painful to rework later. The goal is not to predict every future requirement but to avoid decisions that make the next reasonable change harder. That includes accepting technical debt on purpose: a rough first version can buy customer feedback before a month of polish is spent. Trouble starts when temporary decisions quietly become permanent, which is where a disciplined custom software development partner earns its keep.
Fix the Bottleneck You Have, Not the One You Fear
Growth eventually turns shortcuts into liabilities. Queries that took milliseconds begin to crawl. Background jobs compete with customer requests. A single deployment pipeline becomes a queue. Integrations that once handled hundreds of calls now handle millions.
This is where backend engineering turns evidence-driven. Before redesigning anything, teams need to see where the constraint truly sits:
- Measure First: PostgreSQL’s EXPLAIN ANALYZE, Datadog, New Relic, and OpenTelemetry tracing reveal what an architecture diagram cannot, and good performance work starts there.
- Try the Small Fix: A missing index can matter more than a new caching layer, and moving a slow task to asynchronous processing can cure latency without splitting the application.
- Weigh the Trade-off of Caching: Redis suits a read-heavy workload, though it brings cache invalidation questions of its own.
- Split Services Only for Concrete Reasons: A workload must grow independently, two components have very different availability needs, or teams block one another because every release demands whole-application coordination. “Microservices scale better” is not one.
- Count the Cost of Distribution: Distributed systems trade one set of constraints for another, adding network failures, retries, stale reads and harder debugging. Netflix and Amazon run highly distributed architectures because their size demands it; copying the pattern into a 20-person SaaS company does not recreate the conditions that made it useful.
- Pick Tech by Workload: Scala suits certain concurrent, data-intensive JVM workloads, but it has a smaller hiring pool than Java and adds little to a conventional CRUD application. The stack should follow the workload.
Right Problem, Right Moment: A Backend Priority Map
| Stage | Core Question | Priority That Pays Off |
|---|---|---|
| Early product | Will people use this? | Modular monolith, fast feedback |
| Growth | Where is it slowing down? | Measurement, indexing, async work |
| Expansion | Can it stay up? | Observability and failure handling |
| Maturity | Can it change safely? | Tests, stable contracts, shared tooling |
When Downtime Stops Being Just an Engineering Problem
At some point, an outage stops being an engineering inconvenience. A B2B platform may owe customers contractual uptime. A storefront running Adobe Commerce or Shopify loses revenue the moment it goes down. A failed payment workflow leaves transactions in limbo, and even a short incident floods support queues.
That changes the agenda. Logs alone are not enough when a request crosses several services and outside APIs. Teams need metrics, tracing that follows requests across boundaries, and alerts tied to symptoms customers feel.
Failure handling has to become deliberate too. What happens if Stripe accepts a payment but the application times out before hearing back? What if Kafka delivers a message twice? Retries help, but careless ones amplify an outage. Timeouts stop requests from hanging, though aggressive ones create failures of their own. Idempotency guards against double processing at the cost of extra logic. A reliable system is not one that never breaks; it is one that breaks in ways the business can tolerate.
Technical Debt Is a Price Tag, Not a Smell Test
Debt is easy to discuss as a code-quality issue. At scale, it is usually a productivity issue. Picture an internal library used by 30 services. Its API is awkward but stable, and replacing it would take months, so leaving it alone may be perfectly rational. Now picture a release process demanding the same manual checks for every deployment. As services multiply, that friction is paid again and again, and fixing it may return far more than rewriting the ugly library.
So mature teams do not rank debt by how unpleasant the code looks. They ask what it costs: more incidents, harder security patches, slower onboarding, or teams forced to coordinate changes that should be independent. Every quarter of refactoring is also a quarter of product work not done, so “pay down technical debt” is not automatically good prioritization. The expensive debt goes first.
More Teams, More Problems No Server Can Fix
Traffic is only one axis of growth. Five backend developers can agree on conventions in a meeting; fifty across several teams cannot lean on shared context.
Where Team Growth Creates Drift
- One team picks GitHub Actions while another builds custom Jenkins pipelines
- Services expose metrics differently
- Security settings drift
- Developers keep rediscovering how to provision environments and ship a new service
This is where consistency pays for itself.
How Platform Engineering Helps
Platform engineering exists for exactly this problem. Companies offer reusable CI/CD workflows, service templates, and governed self-service deployment paths instead of asking every team to invent them.
- Gartner projects that 80% of large software engineering organizations will have platform engineering teams by 2026, up from 45% in 2022.
- Google’s DORA research found that 90% of organizations have adopted at least one internal platform, and that platform quality correlates directly with the value teams unlock from AI, so it becomes a prerequisite for any AI and machine learning roadmap.
- Spotify’s Backstage, born as an internal developer portal and now an open-source CNCF project, is a well-known example.
Why Adoption Matters More Than Existence
An internal platform is not automatically a sign of maturity, though. It has to remove friction developers actually feel. A platform team that builds abstractions nobody wants simply creates another product to maintain. Adoption matters more than existence.
The Final Boss Is the Cost of Change
Young companies worry about shipping a feature. Growing companies worry about handling load. Mature companies face a harder challenge: changing a large, important system without breaking it. A platform may hold hundreds of tables, years of customer data, several public APIs and aging links to ERP and CRM systems, each owned by a different team.
Earlier habits compound here. Clear ownership shows who responds to a failure. Automated tests make refactoring safer. Observability reveals what a deployment did. Stable API and event contracts let services evolve without forcing every consumer to change at once, keeping releases seamless. None of this makes change risk-free; the aim is to make routine changes routine.
That is a better maturity measure than counting microservices, Kubernetes clusters, or internal tools. Sustained velocity is the real signal: a backend that handles new requirements without turning each release into an infrastructure project. Some systems need Kafka, Kubernetes, and hundreds of services. Others serve a large business with a well-designed monolith, PostgreSQL, and a disciplined release process.
The Best Backend Is the One Nobody Talks About on Release Day
Backend maturity is not a technology checklist. It is the steady shift from asking whether a product can be built to asking whether it can stay fast, stay up and stay changeable as the business grows. Deciding which technologies have earned their place is easier with a partner that has watched both extremes play out.
Brainvire has delivered 2,500+ enterprise programs, spanning consulting, product engineering, QA and full-stack delivery, with the right talent matched to each workload. Its AI accelerators package playbooks, pre-built components, and AI tooling for legacy modernization, cloud-native re-platforming, and API layers, so structured migrations start from a scaffold instead of a blank page. Each engagement stays outcome-led: the goal is a system the business can change safely, not a longer list of technologies.
Beyond delivery, Brainvire pairs enterprise solutions with engineering across commerce, ERP, and AI, so systems absorb complexity instead of exporting it to every team. Teams weaving intelligence into these systems can also explore its Adaptive AI work, and the case studies show how real programs played out.
To map the next stage of a platform’s growth, book a working session with a Brainvire architect.
Frequently Asked Questions
When should a startup move from a monolith to microservices?
Only when a concrete constraint appears, such as a workload needing independent growth or teams blocking each other’s releases. Until then, a modular monolith is simpler to run, cheaper to operate and easier to change, and it lets a small team ship faster without managing distributed complexity.
What is the most common early backend mistake?
Designing for traffic that does not exist yet. Adding Kubernetes or Kafka before a product finds its audience burdens a small team with operations work that delivers no user value. Early on, flexibility and speed of learning matter far more than raw capacity.
How can teams find the real bottleneck before redesigning?
By measuring first. PostgreSQL query analysis, Datadog or New Relic monitoring and OpenTelemetry tracing show exactly where time is spent. Many problems need a missing index or asynchronous processing, not a new architecture, so evidence should always guide the decision before any redesign begins.
Which technical debt should be fixed first?
The debt with the highest measurable cost: frequent incidents, painful security patching, slow onboarding or forced cross-team coordination. Ugly but stable code that rarely changes can wait, because every refactoring quarter is also a quarter of product work not done.
When does a company actually need platform engineering?
When several teams keep solving the same delivery problems differently, such as pipelines, secrets and environments. At that point, shared templates, reusable CI/CD workflows and self-service paths save real engineering time, reduce drift and help new services reach production faster and more consistently.