Custom generative AI apps
Production GenAI applications built on your data and wired into the tools your Singapore teams already use daily. A running system, not a demo.
Generative and agentic systems put to work on real queues: purchase orders, content operations and customer interfaces, evaluated against a baseline before go-live.
/ What we build
Production generative AI for a regulated, data-conscious market: copilots, agents and retrieval systems built on your data, wired into working systems, and governed for scrutiny.
Production GenAI applications built on your data and wired into the tools your Singapore teams already use daily. A running system, not a demo.
Task-specific copilots and agentic workflows for support, operations and knowledge work, with guardrails your compliance team can stand behind.
Retrieval-augmented generation over your documents and databases, with vector stores that can live in Singapore-region infrastructure where residency matters.
Model selection, fine-tuning and multi-model orchestration balanced across accuracy, latency, cost and where your data is allowed to travel.
Generative pipelines for marketing, product and document workflows, built for teams publishing across Singapore and Southeast Asian markets.
Security, evaluation and model governance shaped for regulated industries, mapped to frameworks Singapore boards and regulators recognise.
/ Global proof, reviewed on Singapore hours
Two cards, both global Brainvire engagements rather than Singapore ones, and neither is a pure generative build. The curated set of client work we show every buyer worldwide, on our homepage and in the main case study library, holds none, so we are not going to invent one. The closest it holds is the first card, where a model reads a purchase order in whatever format it arrives and writes a validated draft order. The second is the data unification work that has to exist before a model has anything reliable to read. Our generative builds themselves — a text to image application on Stability Diffusion, a retrieval-grounded assistant for an ESG risk firm, and an HR assistant moved onto OpenAI — are answered in the questions further down this page, and our documented Singapore delivery is in the Singapore case studies.
 Agentic AIAmerican Lighting PO Automation20–30s per purchase order, down from manual review. An AI-driven, Agentic solution that reads Zendesk purchase orders in any format, reconciles them against business data, and creates validated Adobe Commerce draft orders — 400–1,000 POs a day in ~20–30 seconds each.Agentic AI · Adobe CommerceRead the case →
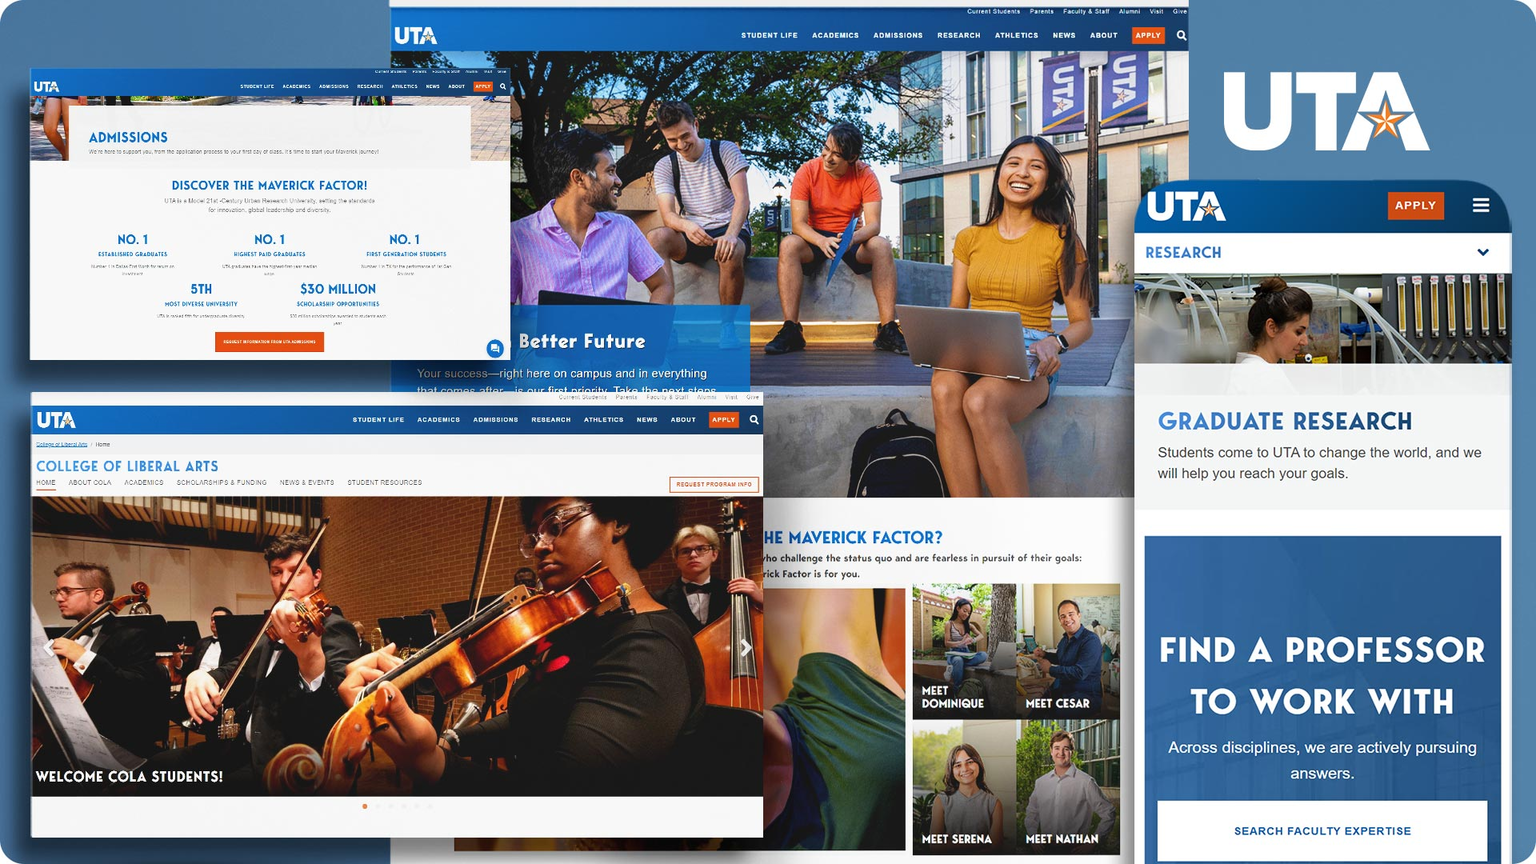 EducationUniversity of Texas20% rise in proposals. We enhanced US university admin processes with a unified web platform, leveraging software expertise. Our experts also improved security with role-based access and university sign-on.Unified faculty data repository · 34% drop in compliance issuesRead the case →
/ Client voices
Named, published reviews from Brainvire clients. Every quote below is reproduced in full on our client reviews page, and the Singapore engagements they refer to are listed on our Singapore case studies page.
/ On the record
By partnering with Brainvire and utilizing their expertise, we were able to successfully achieve our objectives and reduce our manual workload by over 90%.
Brainvire truly understood our needs. They’ve improved our internal operations with better task management, reporting, and efficiency.
Brainvire’s expertise in developing scalable and high-performing mobile applications was a great success for us. No performance hiccups, just happy users.

Significant improvements in code quality and usability, the product no longer crashes and has fewer bugs. Their transparency and commitment to timelines added real value.
Before Brainvire, we had a tough time finding a high-quality software developer. Now, our user churn has dropped from 3.7% to 2.4%, and support-targeted development by 75%. More customers are interested in buying our software.
Brainvire built a really good plan for my business, brought consistency, and took a lot off my hands. I can’t say enough good things.
/ Explore more
/ The Singapore engagement
Generative AI raises one question no other service on this site raises: what leaves the country. Prompts, retrieved documents, embeddings and fine-tuning data are all copies of your information, and each of them travels unless the architecture stops it.
Before a single prompt is written, we sit down at our Singapore office and agree the data map: which corpora the model may read, which fields never leave your systems, and who in your organisation signs that off. Backed by 1,800+ engineers across 10+ offices, but the sign-off happens in the room.
A prompt is a copy of your data and an embedding is a derivative of it. We choose the inference endpoint and the vector store deliberately, favour Singapore-region deployment where residency matters, and document every call that crosses a border so your reviewers are reading a diagram rather than guessing.
Generative AI on the OpenAI partnership, data and lakehouse engineering on the Databricks partnership, one team across both.
Regulated buyers here are asked to show their working. You get the model and version in use, what it was grounded on, what it was never trained on, evaluation results before and after each change, and the actions kept behind a human decision. PDPA obligations are met on the training and fine-tuning data, not only on the answers. Model hosting region, prompt and output logging and retention windows documented for PDPA.
/ Questions, answered
Only if the architecture lets them, which is a choice rather than a given. Enterprise inference endpoints and Singapore-region cloud deployment can keep retrieval stores, embeddings and inference in region. We write down every call that crosses a border, including the ones your reviewers would not think to ask about, such as the embedding step and the evaluation harness. If a use case genuinely cannot be served in region, we say so at design time instead of at security review.
Training and fine-tuning data are a separate obligation from the answers the system gives. We identify which personal data is in the corpus, minimise or de-identify it before it reaches a model where the use case allows, keep a record of what was excluded and why, and avoid tuning on customer records where retrieval over a governed store does the job instead. A model that has memorised personal data cannot be made to forget it on request, which is why this decision is taken first.
Three separate decisions, and buyers usually only ask about the first. The model can be a hosted enterprise endpoint or an open model you run yourself; the vector store can sit in a Singapore cloud region under your own account; the source documents may never need to move at all if retrieval reads them in place. We set each one explicitly and record it, because they carry different residency and different cost.
The model and version in production, what it is grounded on and what it was never given, the evaluation suite results before and after each change, the guardrails and their failure modes, and the list of actions kept behind a human decision. Regulated Singapore buyers are asked to show their working; we build the system so the working already exists rather than assembling it under deadline.
Retrieval grounding first, so answers come from your content with the source attached and a plain refusal when the content is not there. Then evaluation suites that measure accuracy on your own questions before and after every change, so a model swap is a measured decision. Then a human in the loop for anything that moves money, data or a customer commitment. On the ESG assistant that grounding was a retrieval-augmented generation architecture reading the firm’s own published material.
Both, chosen per use case against accuracy, latency, cost and where the data is allowed to travel. Brainvire is an OpenAI partner and also builds on Claude and open models, with data and lakehouse engineering on the Databricks partnership. On the HRMS assistant the model was moved from Google Gemini to OpenAI when the first choice could not hold speed and accuracy together, which is the kind of decision the evaluation harness exists to settle.
Systems are built model-agnostic wherever practical, with the prompt layer, the retrieval layer and the evaluation suite kept separate from the model itself. When a newer model appears it is run against your own benchmark before anything switches, so adoption is a measured decision rather than a reaction to a launch. Residency constraints are re-checked at the same time, because a new model often means a new endpoint in a new region.
/ Next step
A 30-minute working session with a principal architect, scheduled on Singapore time: your stack, your constraints, and where generative AI fits. No sales deck.
Scope your first generative AI build →Cookies on this site
Essential cookies are always on. They keep the site secure and make forms work.
We also use Google Analytics and Microsoft Clarity to see how the site is used. We only turn these on if you accept.